Home / Computing / GPU clusters
GPU clusters
More servers.
One connected system.
Take work beyond a single server. Dedicated GPU servers, high-speed networking and storage are designed and tested as one system in one location.
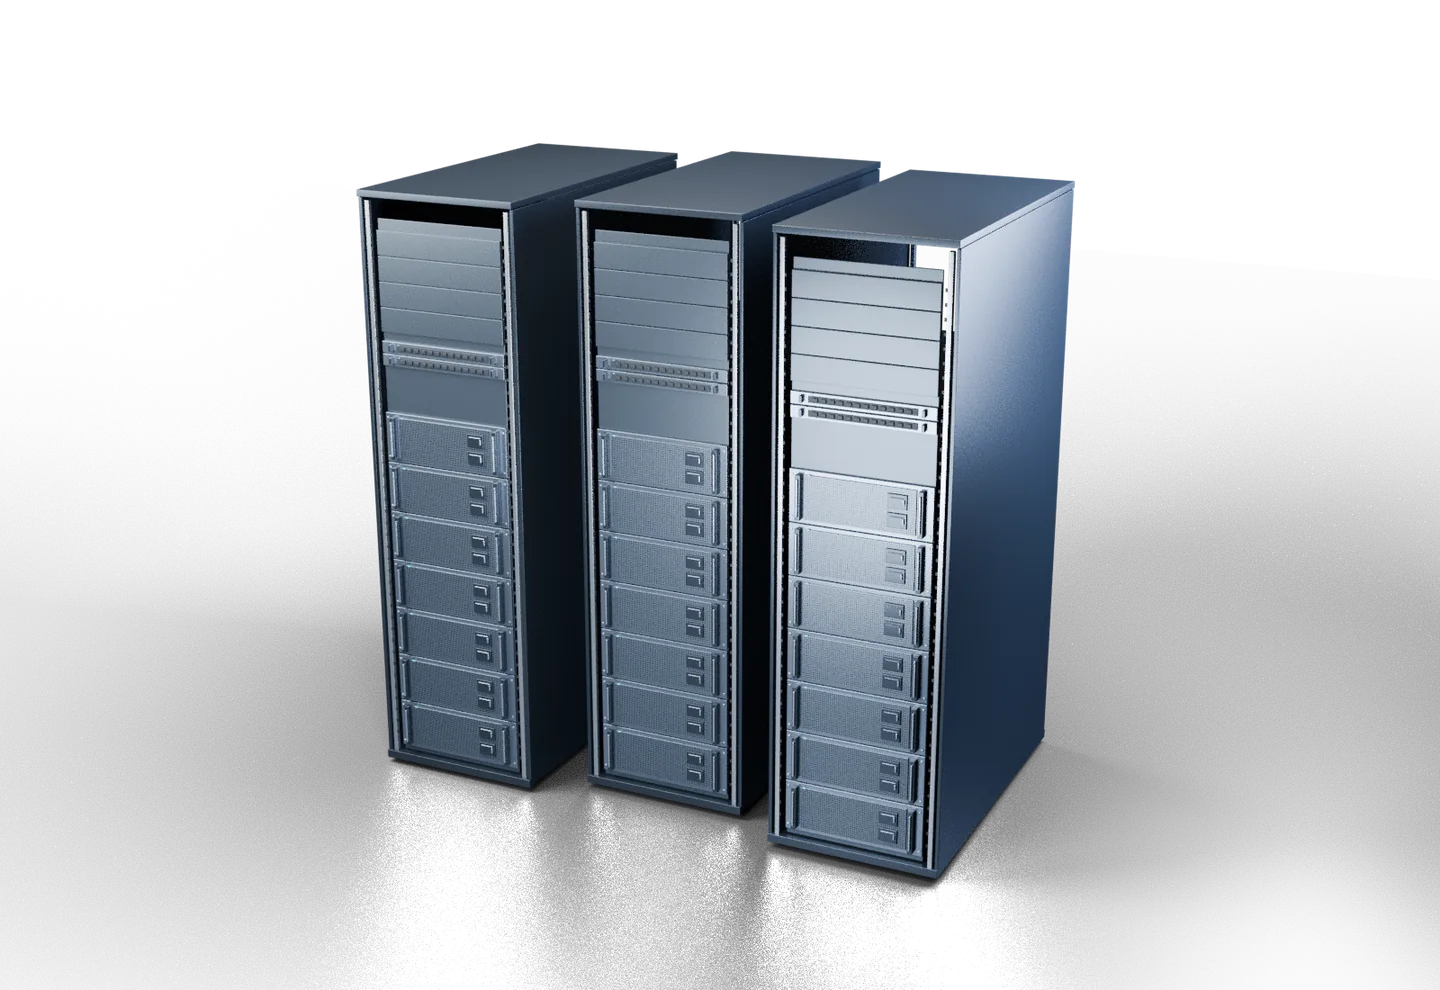
A 32-GPU EXAMPLE
Four nodes.
A dedicated fabric.
Four 8-GPU B300 servers connected within one location. The fabric, switch layout and storage are selected for the workload.
Example topology. The final design and complete server specifications are agreed in the proposal.
 NODE 018 × B300NODE 028 × B300NODE 038 × B300NODE 048 × B300
Compute nodes
Exact GPU configuration, host resources and number of servers.
GPU fabric
Port speeds, switching, topology and any oversubscription, validated for the workload.
Access & storage
Local NVMe, shared storage or a parallel file system, with a route for loading data and checkpoints.
32 GPUs in one connected deployment
Choose the architecture
A cluster does more
than add servers.
For jobs that exchange data between machines, the connections and storage become part of the computing system.
Compare independent servers and a connected cluster
| Independent servers | Connected GPU cluster | |
|---|---|---|
| Best suited to | Inference replicas, separate rendering jobs and work that fits one server. | Training and other distributed workloads that exchange data across nodes. |
| Network | Front-end Ethernet for access and data transfer. | Dedicated inter-node fabric, plus front-end connectivity. |
| Acceptance | Each server meets the agreed specification. | The whole system passes the agreed compute, fabric and storage tests. |
Your cluster specification
Every connection counts.
A cluster brings the nodes, fabric and storage together. We assess HGX, AMD Instinct and suitably networked RTX PRO configurations for the work you need to run.
- 01Compute nodes
Exact GPU configuration, host resources and number of servers.
- 02GPU fabric
Port speeds, switching, topology and any oversubscription, validated for the workload.
- 03Storage and ingestion
Local NVMe, shared storage or a parallel file system, with a route for loading data and checkpoints.
- 04Platform and access
Operating system, GPU software, access and any separately agreed scheduler setup.
- 05Acceptance
Compute, fabric and storage checks, plus your benchmark where agreed.
The reference RTX PRO server with 2 × 25 GbE is a standalone configuration. An RTX PRO cluster requires a separately validated server and network design. Tightly coupled clusters operate within one location.
Cluster pricing
Quoted for the configuration, operating location, service scope and term you choose. Your offer identifies the delivery window and any upfront payment.
Plan your cluster.
Bring the model and the scale. We’ll work through the network, storage and timing with you.